Benchmark run
2026 09 v2 large v2 q5 0
benchmark-v2 publication batch 2026-09-v2; codictate large-v2-q5_0; clips [0, 400) of the consumable range; hotkey option+z
Sep 5, 2026
- Models
- 1
- Samples per dataset
- 400
- Warmup runs
- 3
- Hardware
- Apple M4 Max / 36 GB / macOS 26.6.2
Full results
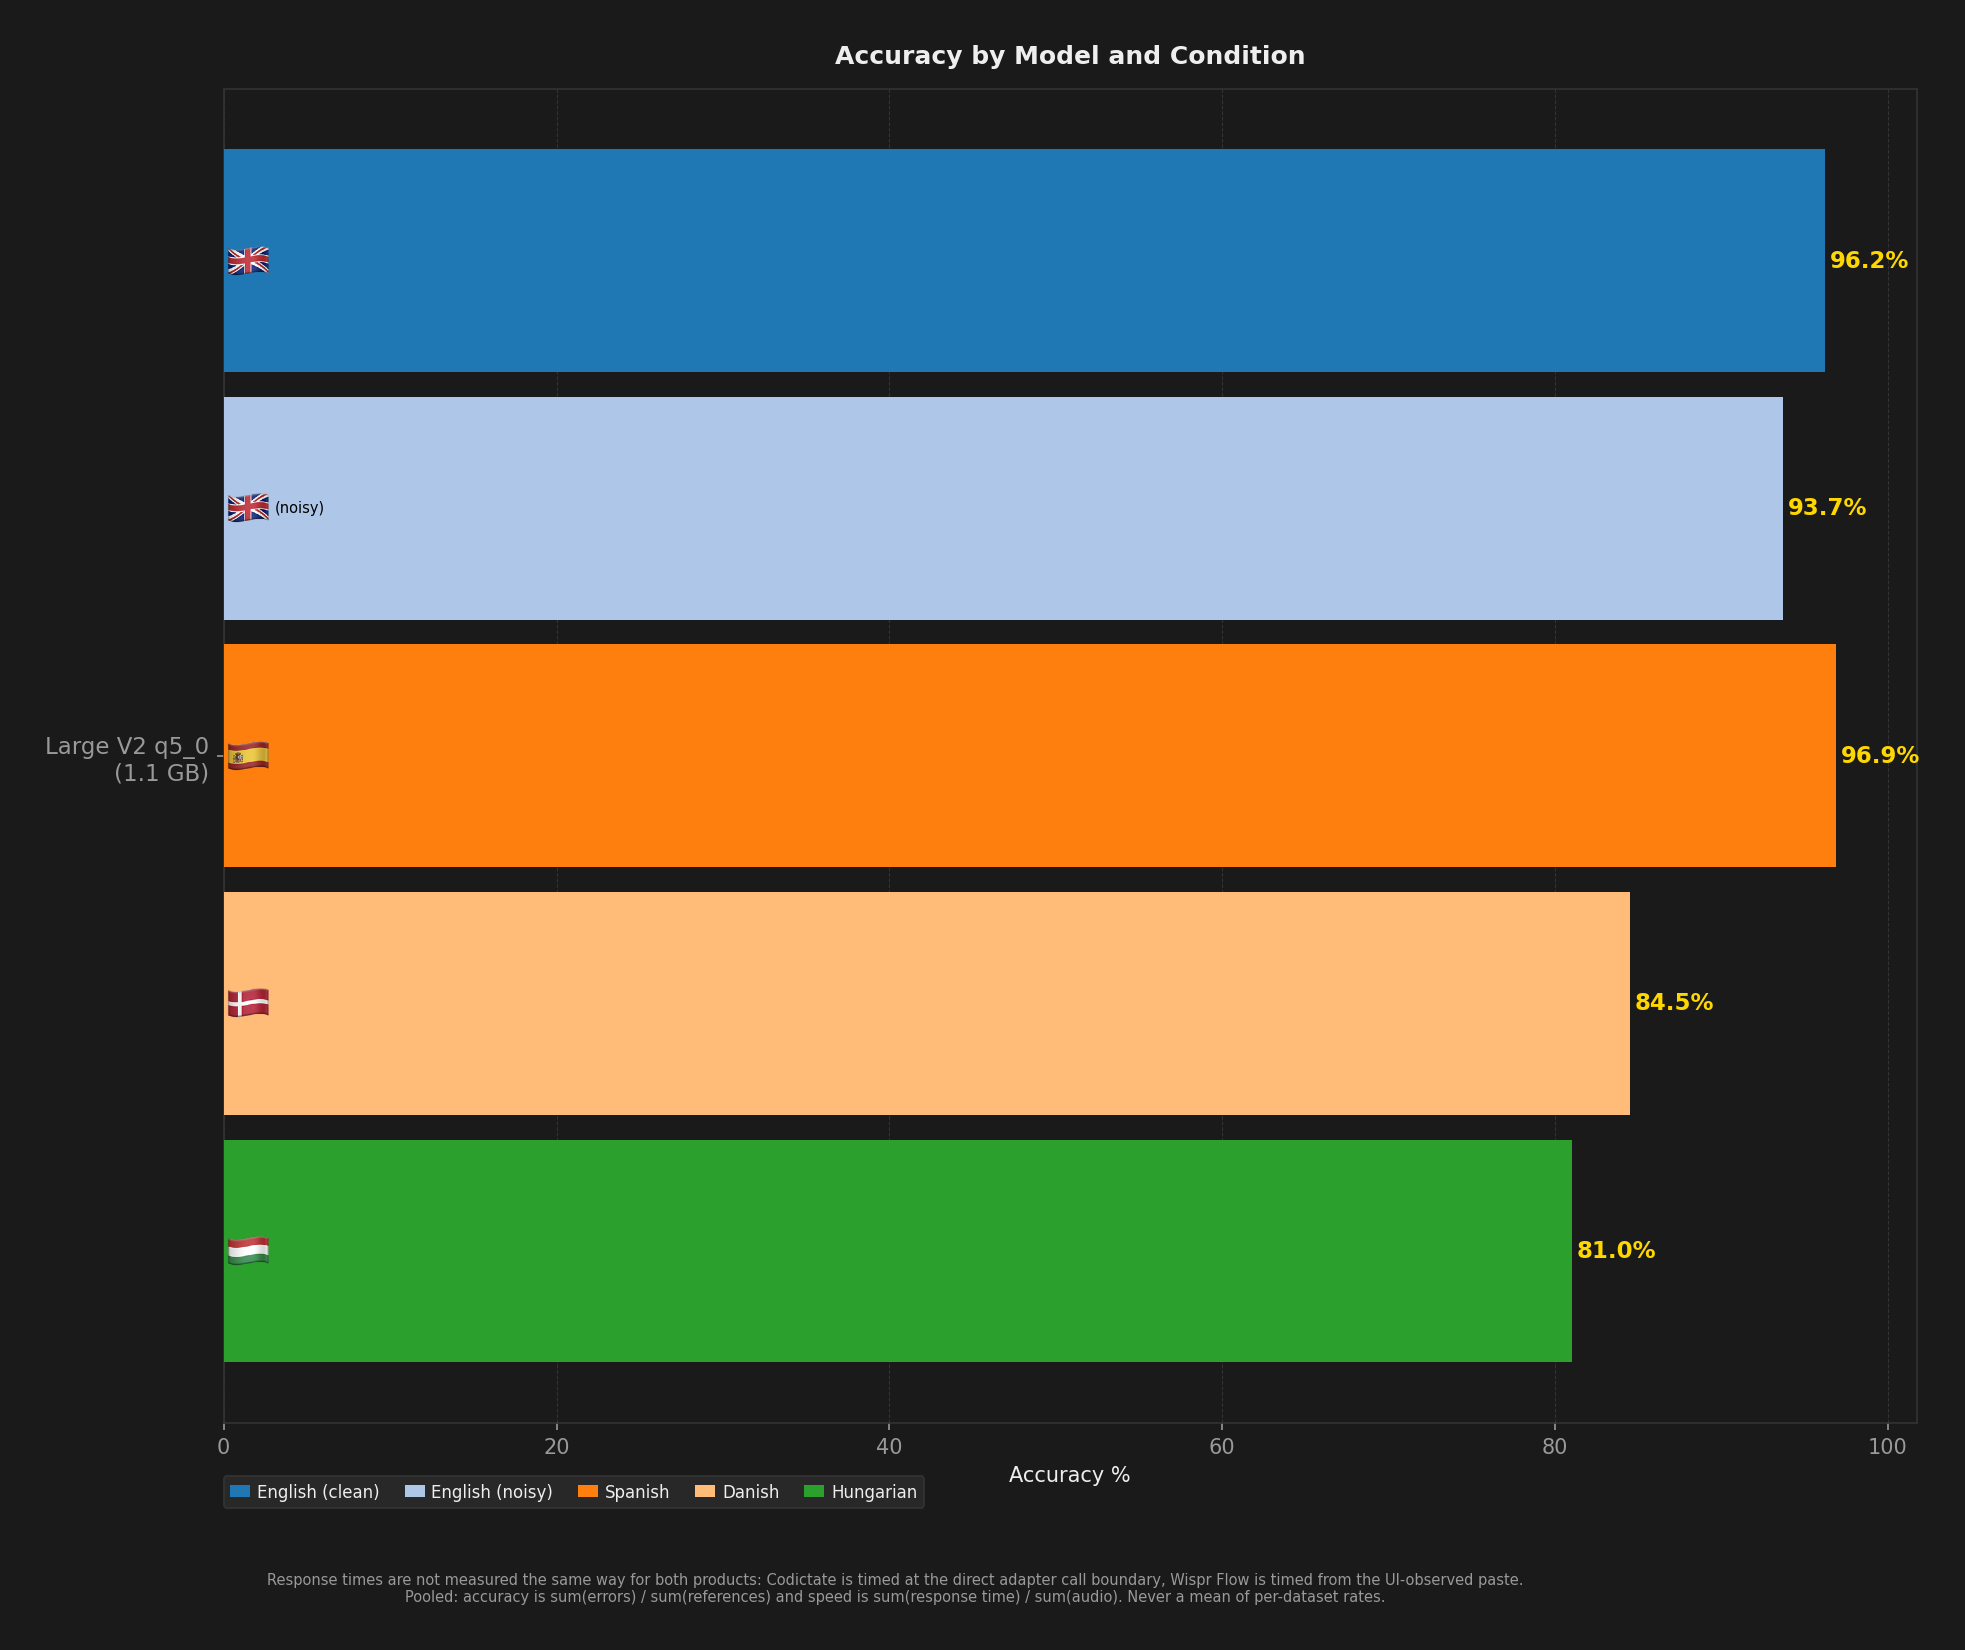
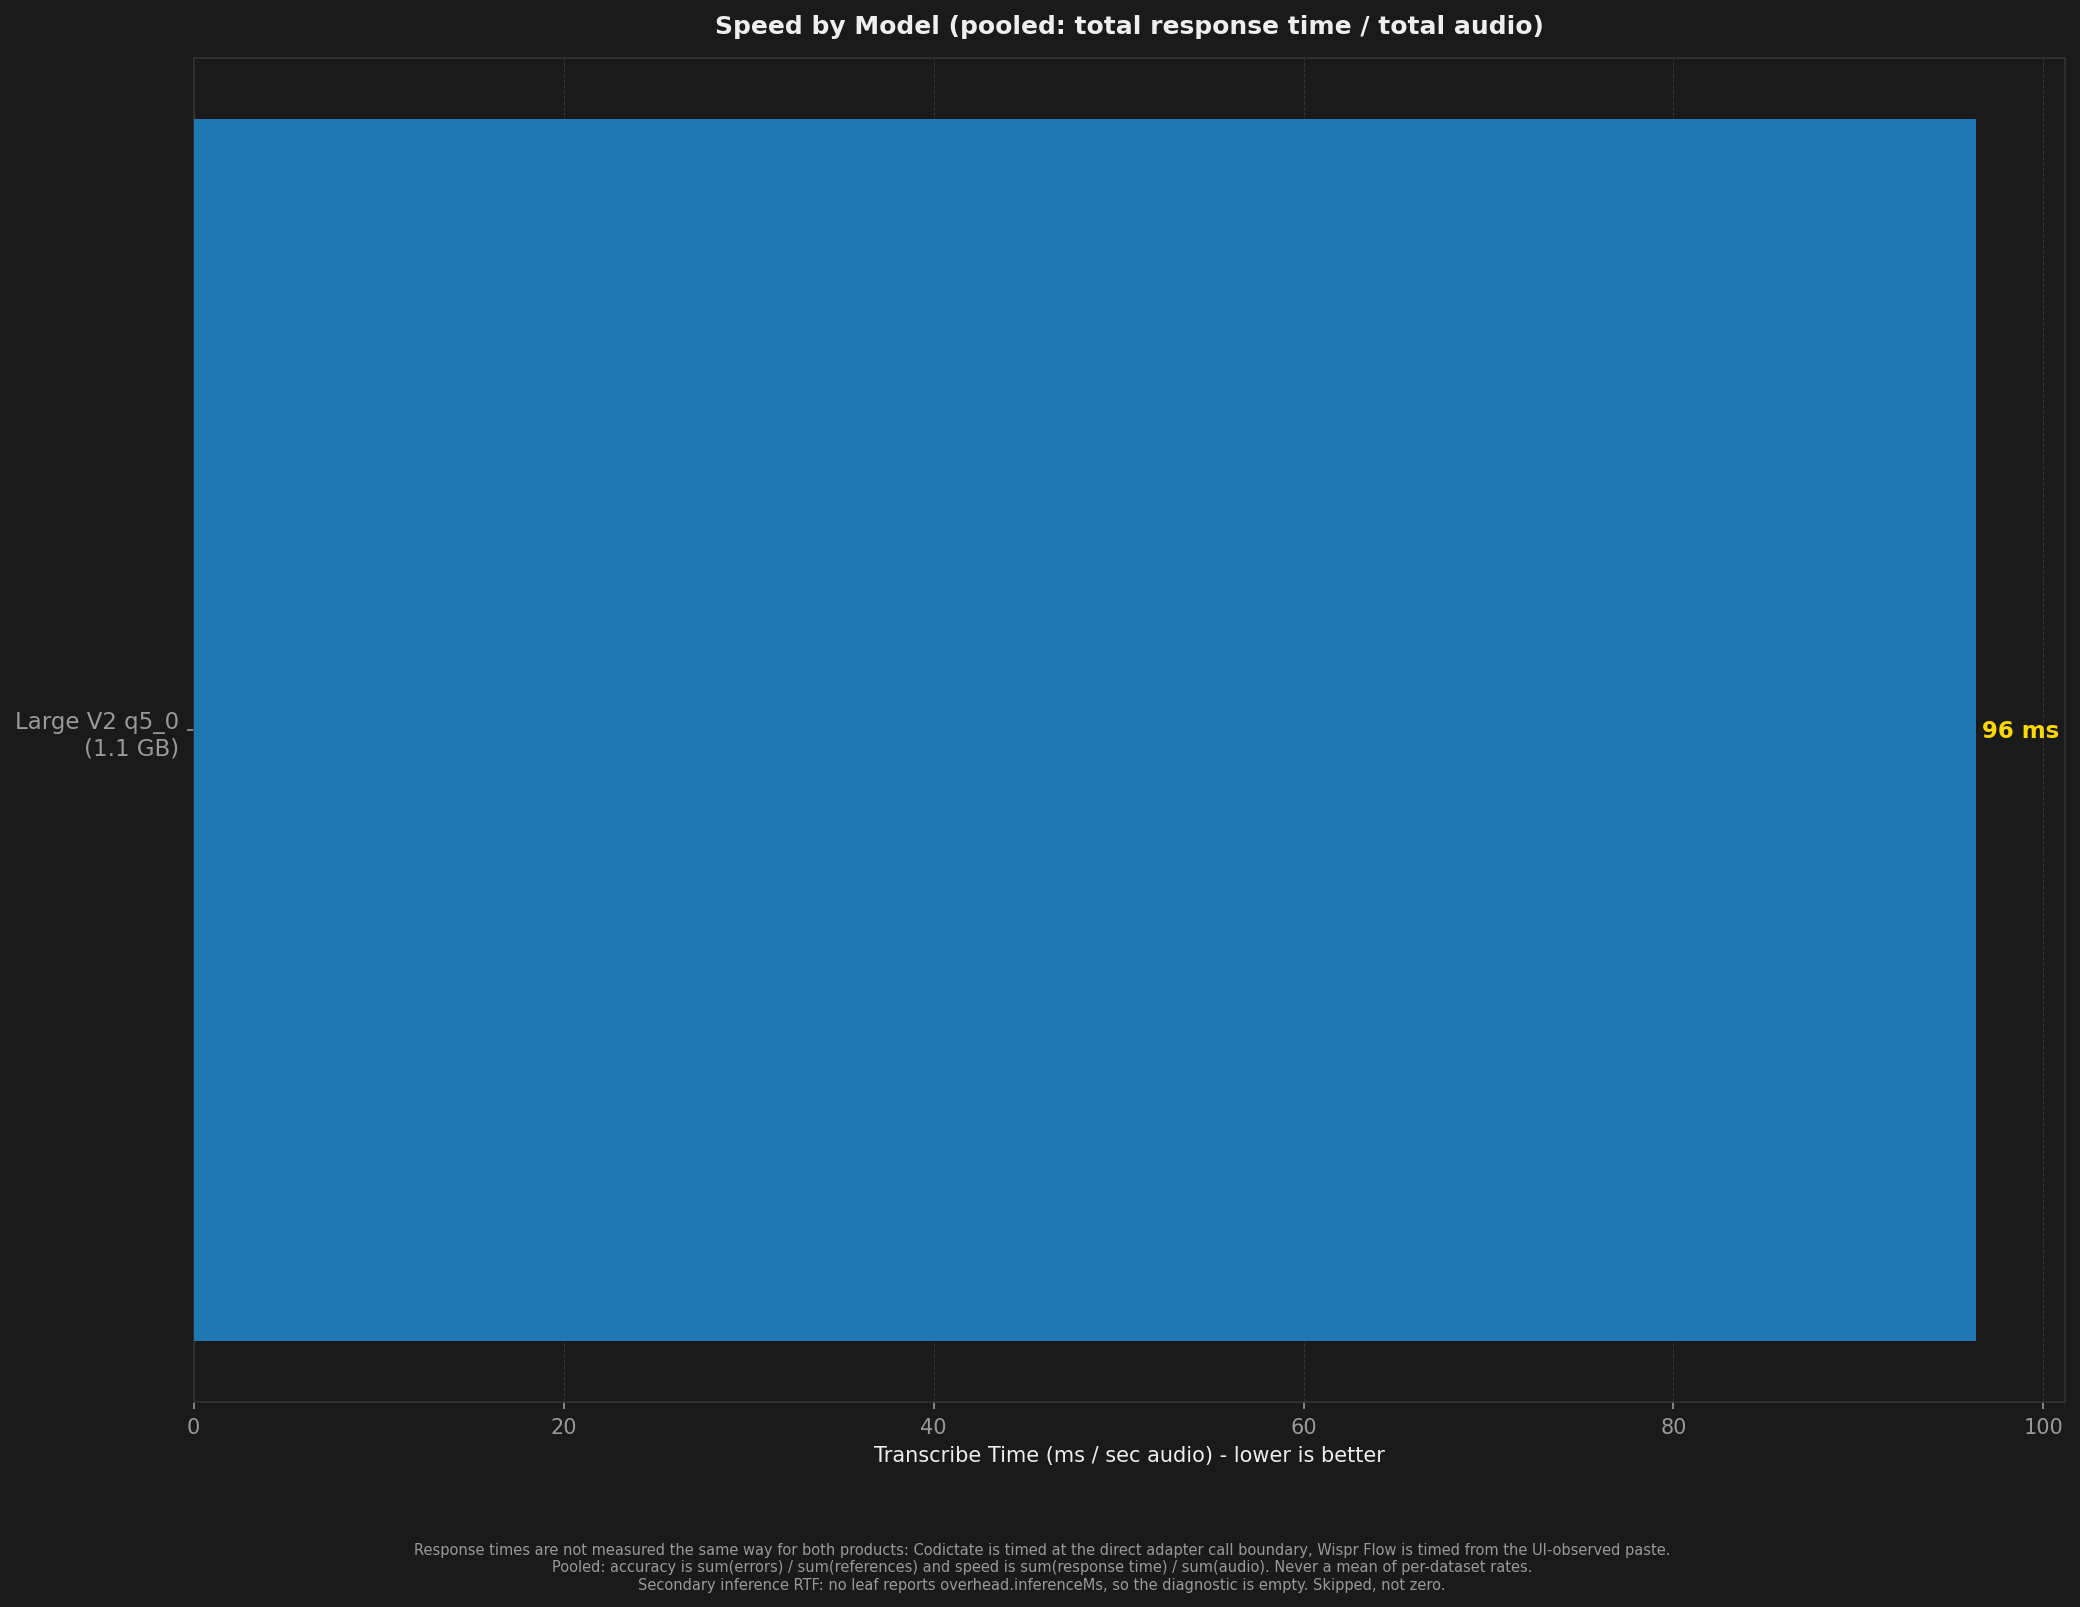
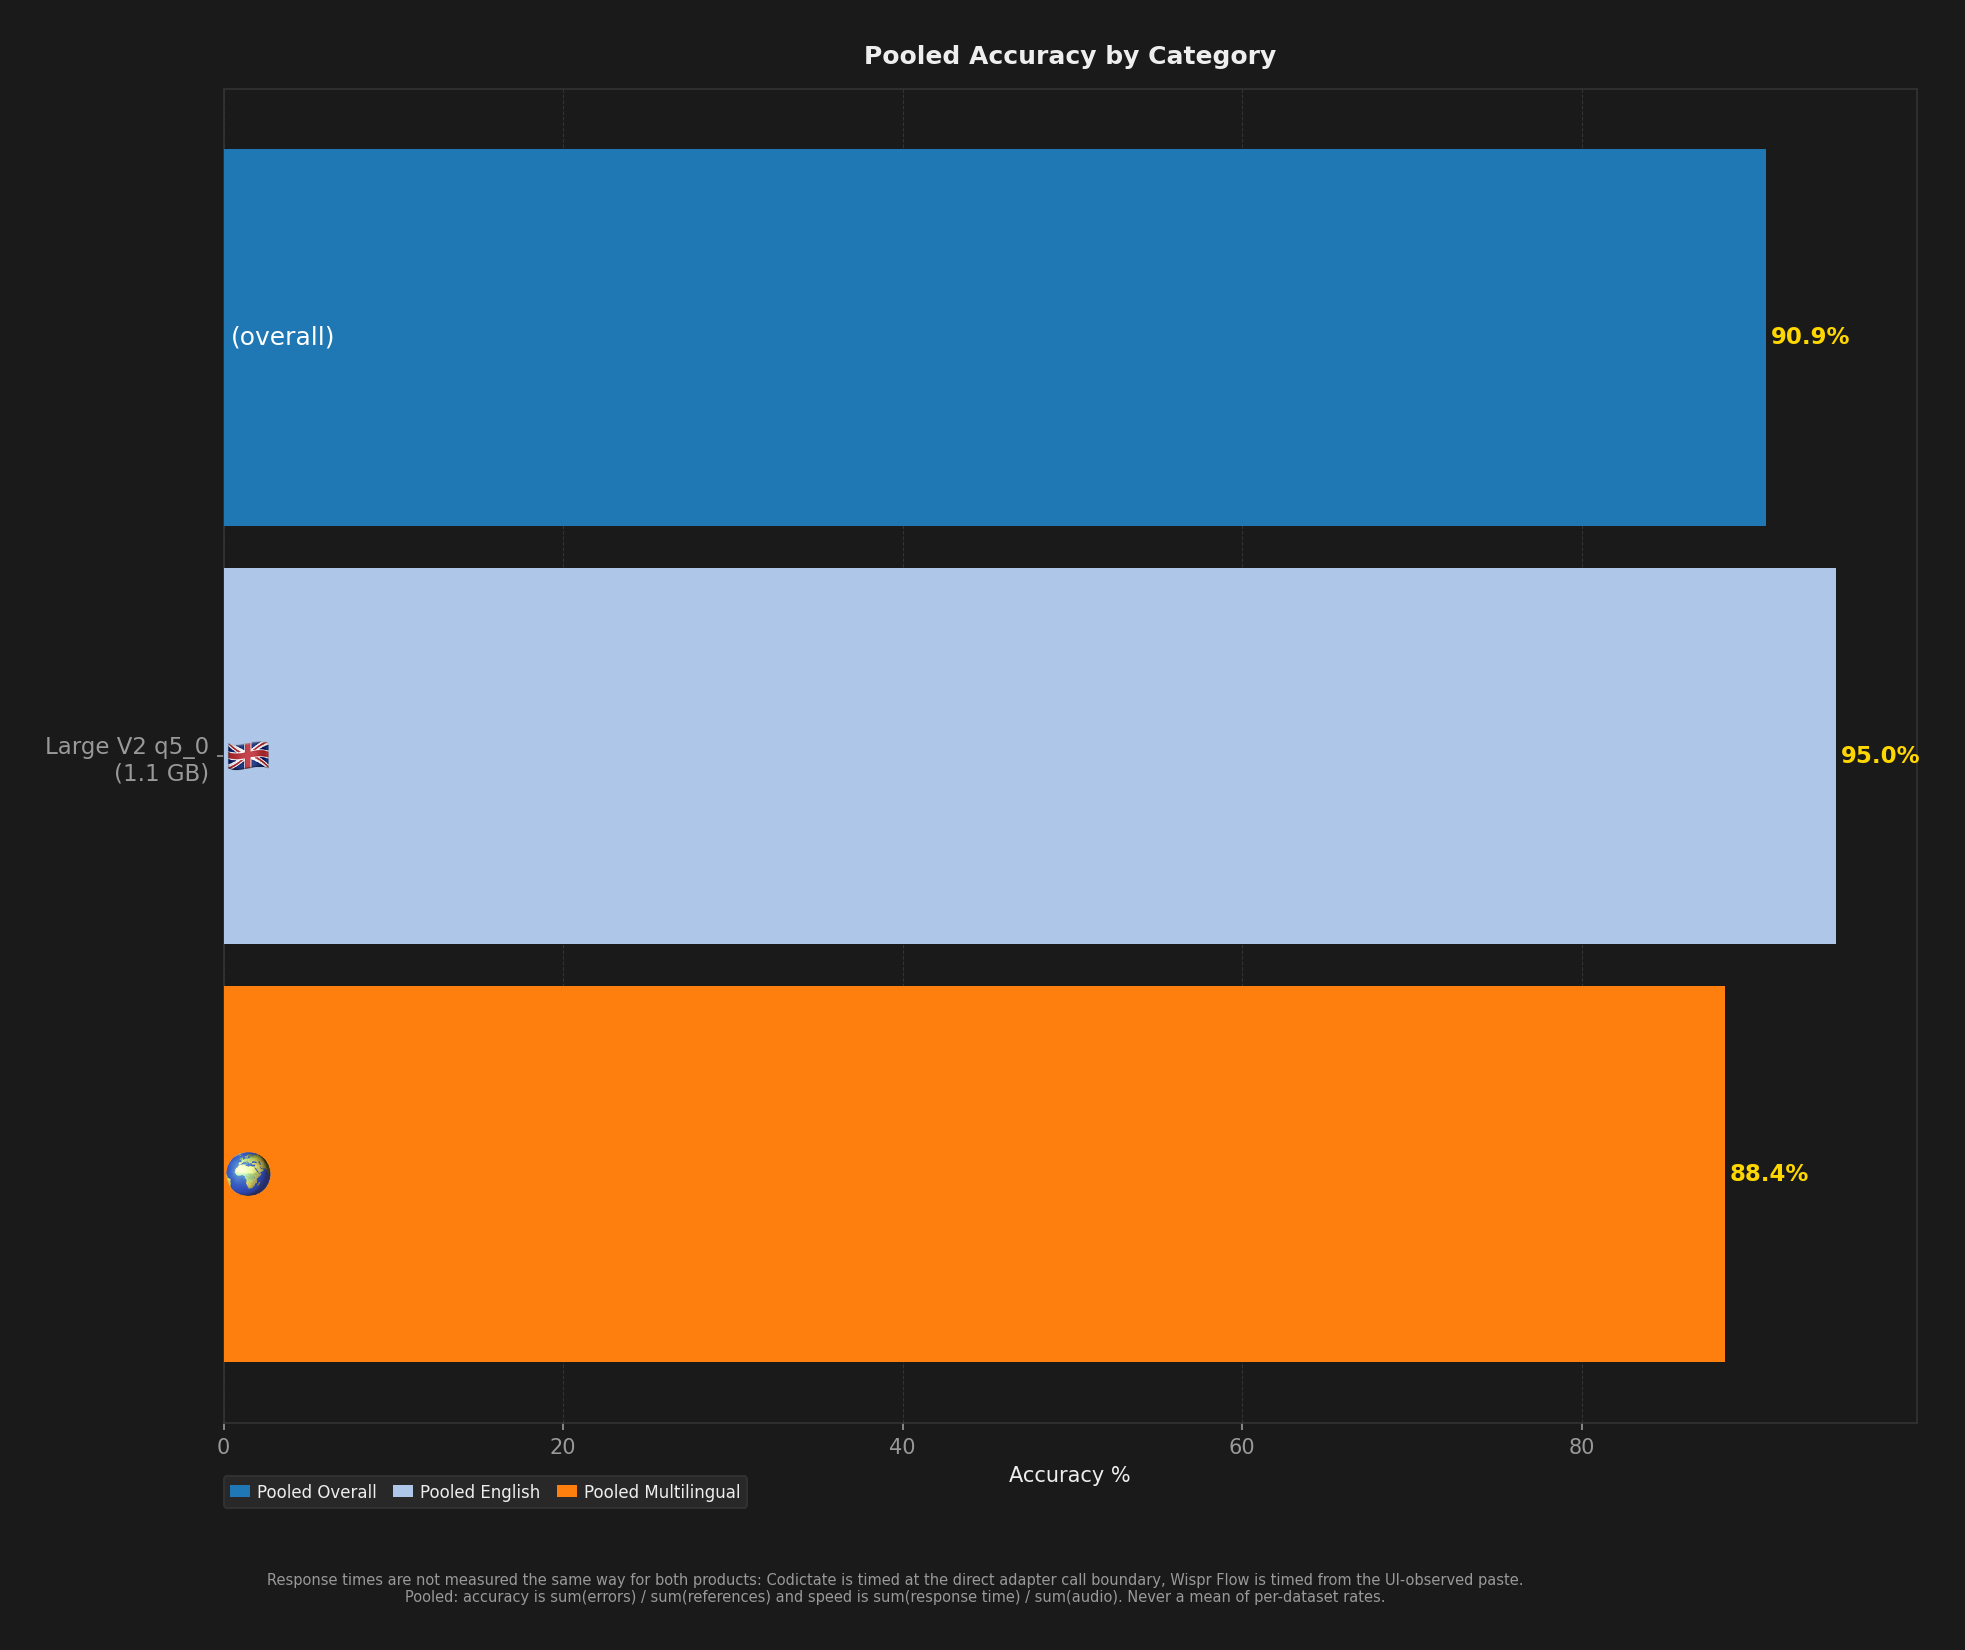
Accuracy is the share of words transcribed correctly per language condition, so higher is better; speed is milliseconds per second of audio, so lower is better. The best value in each column is emphasised, and a cell reading a dash says on hover why there is no figure in it.
Accuracy (%) per language, and speed in ms per second of audio, so lower is better. A cell reading a dash was never measured, and hovering any cell says what is behind it.
| Whisper Large V2 Q5_0 | 400 | 1.1 GB | 1.5 GB | 96 ms | 90.9%Every word from every language counted together, not an average of per-language scores. | 95.0%Every word from every language counted together, not an average of per-language scores. | 88.4%Every word from every language counted together, not an average of per-language scores. | 96.2% | 93.7% | 96.9% | 84.5% | 81.0% |
|---|
At a glance
Ratings computed from benchmark data, scaled 1 to 10, and written with their scale in every cell. Accuracy is based on Word Error Rate (WER) and does not include punctuation yet.
Ratings run 1 to 10, higher is better. A cell reading a dash was never measured, and hovering any cell says what is behind it.
| Whisper Large V2 Q5_0 | All languages | Yes | 8/10 | 9/10Every word from every language counted together, not an average of per-language scores. |
|---|
Charts
The plots generated alongside this run. Select a chart to open it full size.